From Raw Data to Reliable Decisions: Five Functions of a Data Engineer
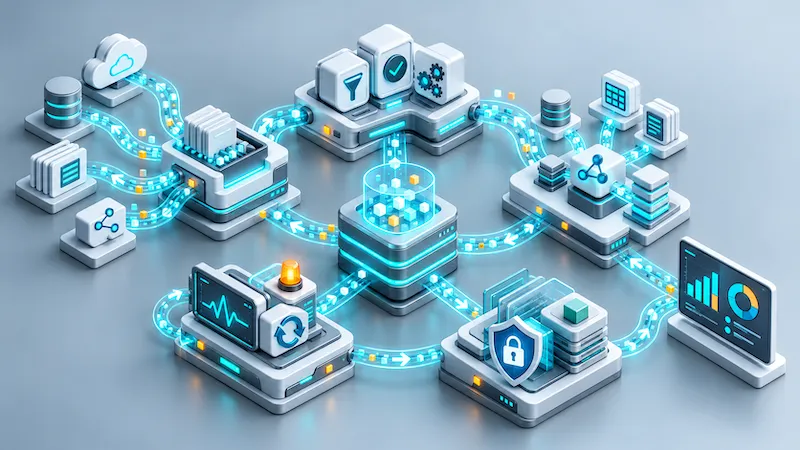
A company may have information spread across its CRM, ERP, payment platforms, advertising accounts, internal files, and operational applications. However, having data does not mean that the organization can use it effectively.
Before information reaches a report or dashboard, it must be collected, stored, validated, transformed, documented, and delivered reliably. That entire process must also continue working when a source changes, an execution fails, or the number of consumers increases.
This journey represents an important part of a data engineer’s work. The role is not limited to moving information between systems. It involves turning that movement into an operational capability that the organization can understand, control, and maintain.
1. Get Data Where It Can Be Used
The first responsibility is to collect information from the correct sources and move it into an environment where it can be processed safely.
Sources may include APIs, databases, internal applications, files, legacy systems, queues, or cloud services. The ingestion process must account for authentication, usage limits, pagination, incremental updates, and temporary interruptions.
When external platforms are the primary sources, reliable API integration must account for authentication, pagination, usage limits, structural changes, and incomplete executions.
Moving data does not mean copying everything during every execution. A reliable process should know what has already been received, what changed since the last confirmed execution, and how to avoid duplicates when a task needs to run again.
It is also useful to preserve a controlled copy of the original data. This makes it possible to investigate source changes, correct transformation rules, and reprocess previous periods without depending on another download.
2. Turn Raw Data Into Usable Information
Raw data rarely arrives ready for analysis. Dates may use different formats, customers may have several identifiers, and the same currency or status may be represented differently across systems.
A data engineer implements rules to correct types, standardize values, remove duplicates, resolve relationships, and verify that the information meets expected conditions.
This stage also includes questions such as:
- Did all required columns arrive?
- Are the primary identifiers present?
- Do dates and amounts use valid formats?
- Is the received volume within a reasonable range?
- Is an important file, period, or category missing?
- Can related records be connected correctly?
Technical rules should not invent business definitions. Concepts such as an active customer, confirmed sale, or profitable campaign must be agreed upon with the appropriate business owners.
The role of data engineering is to apply those definitions consistently and make their implementation testable and traceable.
3. Add Value and Make Data Available
A pipeline should not be limited to moving and cleaning information. It can also combine sources to create a more useful representation of the business.
For example, CRM data may be connected with payments, advertising campaigns, and operational activity. This combination can produce insights and metrics that no individual source could provide on its own.
Data enrichment may include:
- Connecting customers across different systems.
- Categorizing transactions or products.
- Standardizing locations, currencies, and reporting periods.
- Adding reference attributes or classifications.
- Calculating previously approved business metrics.
- Preparing models for sales, finance, marketing, or operations.
The prepared information must then be made available to its consumers. The destination could be a dashboard, analytical warehouse, operational application, file, or API.
Each delivery method should define how frequently the information is updated, what its fields mean, and under what conditions the data is considered available.
4. Manage Data Responsibly
Data engineering also involves decisions about security, privacy, documentation, discovery, retention, and governance.
Not everyone should have access to all available information. Permissions should reflect real responsibilities and follow the principle of least privilege. Sensitive data should be protected during transfer and storage and excluded from environments where it is not required.
Responsible data management should make it possible to answer basic questions:
- Where did this information come from?
- Which transformations were applied?
- Who is responsible for its definition?
- Which teams, applications, or reports use it?
- How long should it be retained?
- What would happen if the source became unavailable?
- Who is allowed to access or modify it?
Cataloging, documentation, and data lineage are not administrative tasks separate from the pipeline. They are part of what allows the team to investigate errors, evaluate changes, and transfer the system to another provider or internal team.
5. Turn the Pipeline Into a Production Capability
A process that works manually on its creator’s computer is not yet an operational capability.
Moving a pipeline into production means automating its execution, managing dependencies, recording results, and responding when something fails. It also requires documentation that allows the workflow to operate without depending entirely on the person who created it.
At minimum, a production pipeline should record:
- When each execution started and finished.
- How many records were received and processed.
- Which validations were completed.
- Which task failed and why.
- Which executions can be repeated safely.
- Who should receive an alert.
- How incomplete data can be recovered.
- Whether the process finished within the required timeframe.
Monitoring should not only confirm that the process executed. It should also detect when a source stops updating, when the volume changes unexpectedly, or when the results arrive too late to support the intended decision.
The Value Comes From the Complete Journey
These five responsibilities form a single system.
There is little value in storing data that nobody can interpret, transforming information without controlling its origin, or producing business metrics that silently stop updating.
A data engineer connects these responsibilities so information can arrive, become usable, gain business value, remain controlled, and operate reliably in production.
The specific tools may change according to volume, frequency, existing infrastructure, and budget. The important requirement is that the architecture supports the complete journey without introducing unnecessary complexity.
Evaluate the Data Workflow Before Choosing the Tools
Does your team spend too much time extracting, correcting, and combining information before it can be analyzed?
Cooltimedia can help you evaluate the sources, transformation rules, operational risks, and production requirements involved in turning that process into a maintainable data system.
Frequently Asked Questions
What Is the Difference Between a Data Engineer and a Data Analyst?
A data engineer builds and maintains the processes that collect, validate, transform, and deliver information.
A data analyst uses that information to study results, identify patterns, and support business decisions. The two roles collaborate closely but work on different parts of the data journey.
Does a Data Engineer Also Build Dashboards?
A data engineer may help define the models and metrics that support a dashboard. However, the role usually focuses on the infrastructure, quality, availability, and reliability of the underlying data.
Visualization may be handled by a data analyst, business intelligence specialist, or another member of the team.
Is Building Pipelines the Only Responsibility of a Data Engineer?
No. Pipelines are an important part of the role, but data engineers may also work on data models, quality controls, storage architecture, security, documentation, governance, cost optimization, and system integration.
This article focuses specifically on the responsibilities required to move data from its original sources into reliable production use.
Do All Data Pipelines Require Complex Tools?
No. A small pipeline can be implemented with a scheduled script if it includes validation, execution logging, error handling, and recovery.
The level of complexity should respond to operational requirements rather than the popularity of a particular tool.
When Does a Company Need a Data Engineer?
A company may benefit from data engineering when information must be consolidated repeatedly, reports depend on fragile manual work, several systems need to be integrated, or data quality problems affect decisions.
Jair Manuel Poveda Frago
Python & Django Engineer
Desarrollador Python y Django, fundador de Cooltimedia y profesor universitario. Especialista en arquitectura de software, IA y soluciones de datos. Conecto la ingeniería aplicada en proyectos reales con la docencia universitaria, compartiendo aprendizajes sobre desarrollo profesional, automatización y buenas prácticas de ingeniería.